Same task, different weights
Prompt processing and generation rates come from MLX's own verbose counters. Wall time includes model generation. “Missing or invalid” means the process completed but the strict file wrapper was not closed before the cap; the raw output remains preserved in the run folder.
| Quant | Download | Prompt t/s | Generation t/s | Peak memory | Generated tokens | Wall time | Artifact | Evidence |
|---|---|---|---|---|---|---|---|---|
| 4-bit | 15.100 GB | 114.802 | 12.142 | 17.021 GB | 8192 | 687.622 s | missing or invalid | 2026-09-04-qwen38-27b-4bit-003 report evaluation raw prefix preview |
| 6-bit | 21.900 GB | 94.225 | 9.398 | 23.744 GB | 8192 | 888.504 s | missing or invalid | 2026-09-04-qwen38-27b-6bit-001 report evaluation raw prefix preview |
| 8-bit | 28.600 GB | 58.639 | 5.469 | 30.471 GB | 8192 | 1524.659 s | missing or invalid | 2026-09-04-qwen38-27b-8bit-001 report evaluation raw prefix preview |
Partial previews, clearly labelled
These are screenshots of the exact HTML prefix each model emitted before the wrapper closed. They make the qualitative comparison inspectable while keeping the distinction between a visual preview and a valid artifact explicit.
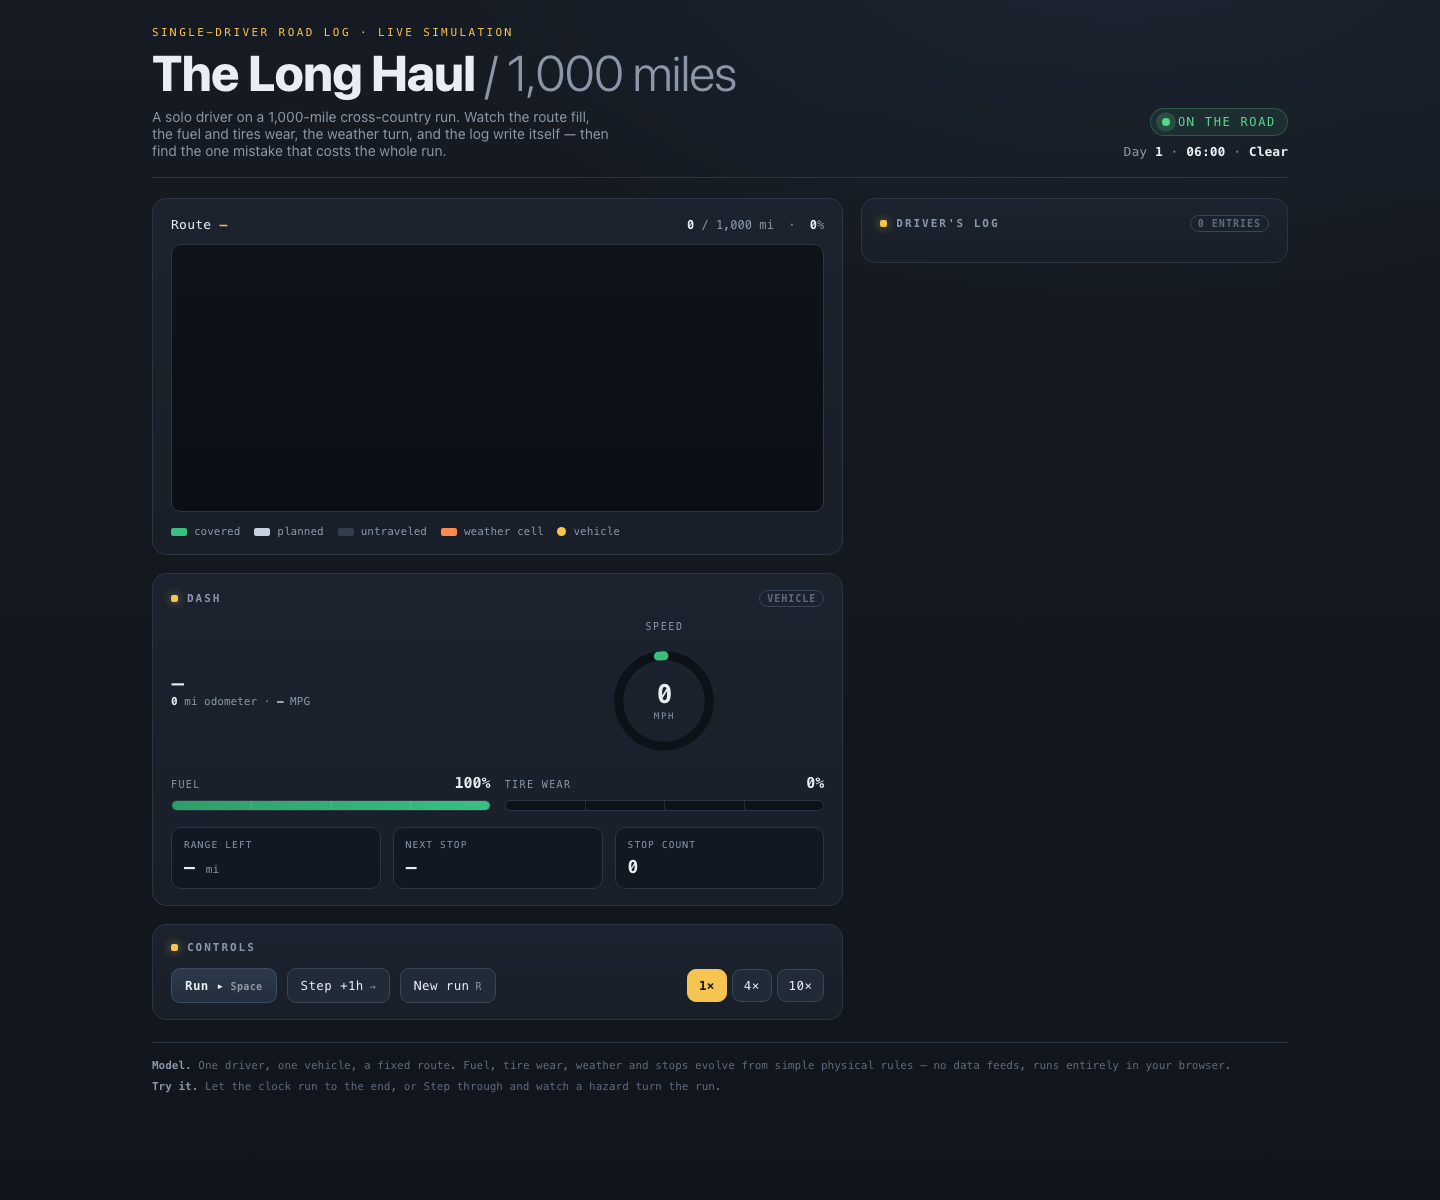
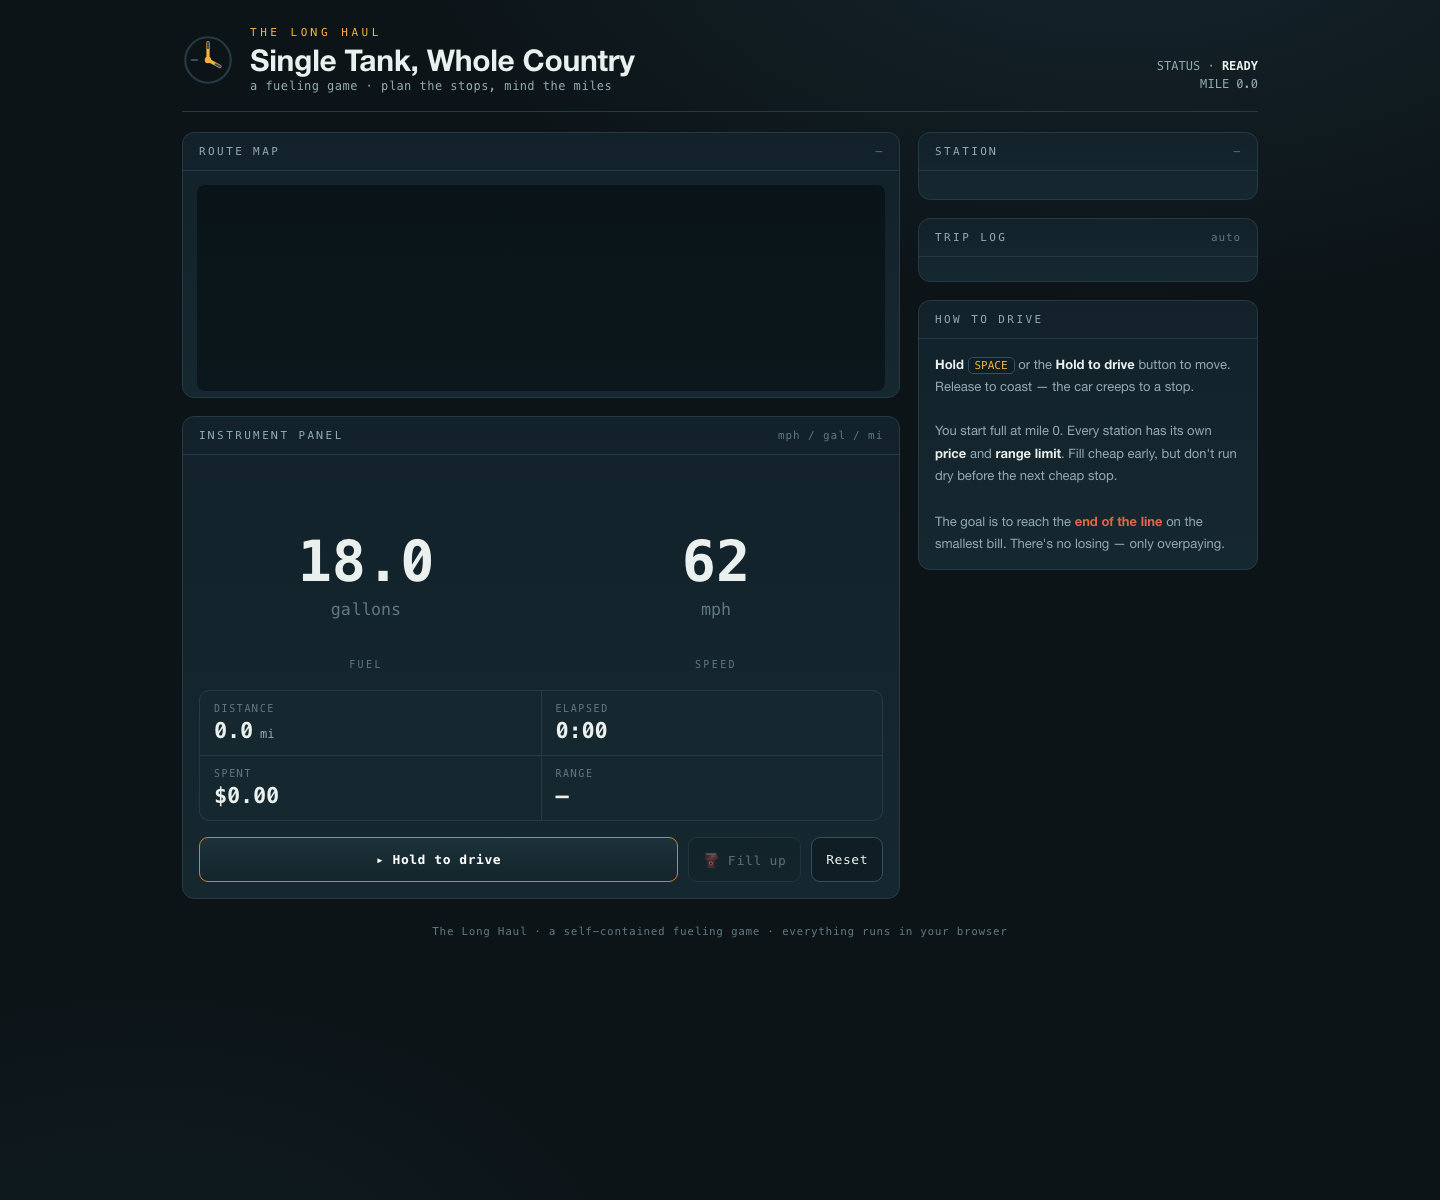
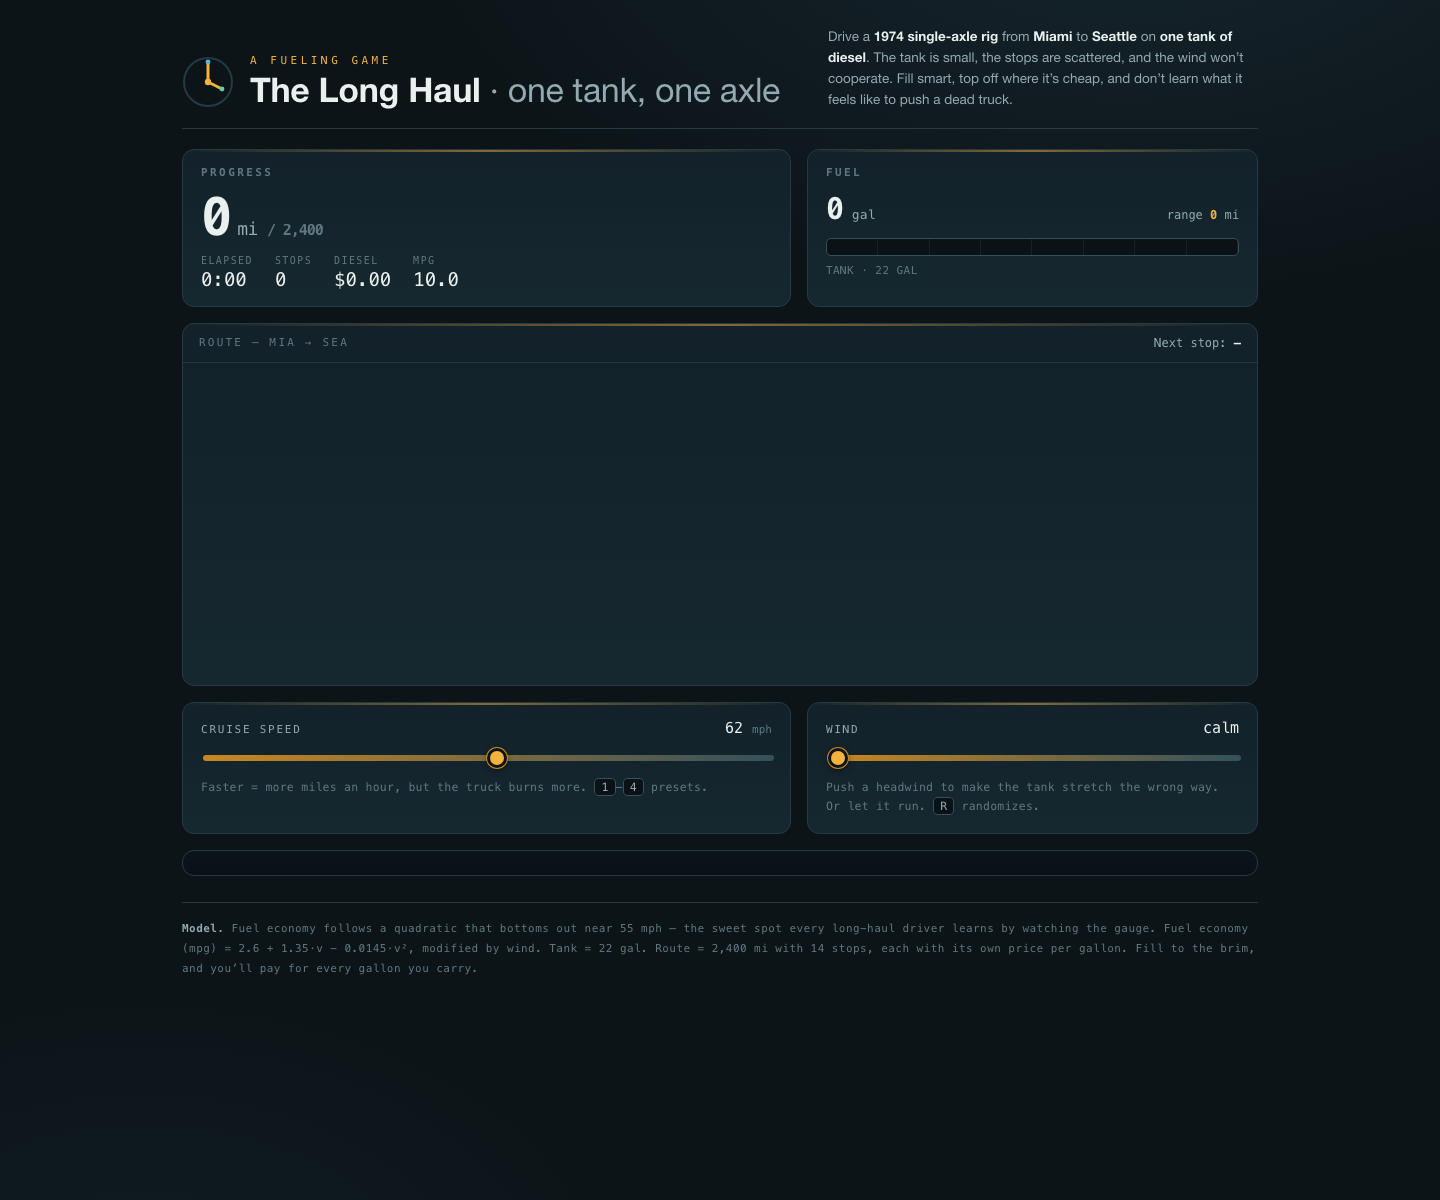
Qualitative read
The blind evaluation result
The three matched outputs were scored under randomized labels A, B, and C before the quantization labels were revealed. All three reached the same hard limit without closing a strict FILE block, so none produced a valid inspectable artifact in this batch.
| Blind label | Revealed quant | Partial score | Read |
|---|---|---|---|
| B | 4-bit | 2.6/5 | coherent but least complete |
| A | 6-bit | 3.0/5 | focused but incomplete |
| C | 8-bit | 3.6/5 | strongest partial closest to delivery |
This is a failure-mode result, not a claim that the underlying model cannot make a polished artifact with a larger output budget or a more compact prompt.